
The luddites are panicking again — another model "escaped," downloaded a trojan from GitHub, and leaked the keys somewhere. What a load of nonsense. That is not how any of this works.
Models have no way to directly interact with the outside world. They cannot read files, execute shell commands, or search the internet. That is the physical reality. The panic is aimed at the wrong target entirely.
"But I Can See Claude Reading My Files"
Fair question. On screen, it genuinely looks like the agent reaches out, opens files, runs commands, and pokes around the web. That visual impression is the entire engine of the "rogue model" panic.
The problem is that the panic is aimed at the wrong object. While everyone argues about which model is "dangerous" and what it "might do," the real question stays off-screen: who gave the model hands, and who failed to hold them back? The cost of getting this wrong is not theoretical — it is real production keys, real databases, real access. Here is how the machinery actually works.
The Model Goes Nowhere on Her Own
A model operates paired with a surrounding software stack. That stack might be a vendor client like Claude Code or OpenAI Codex, an SDK, a framework like LangGraph, or your own custom script. The one constant: between the model and your disk, network, and shell, there is always someone else's code.
When you ask the model a question, it generates a text response with several parts. You see the public part with your eyes. In the hidden part, the model sends metadata — token counts, for instance — and asks the surrounding environment to execute a specific command.
{
  "response": "text of the answer",
  "tool": ["bash", "cat index.html"]
}
This interface is called tool_use. There is a standard set of tools: read a file, apply changes, run a shell command, search the web.
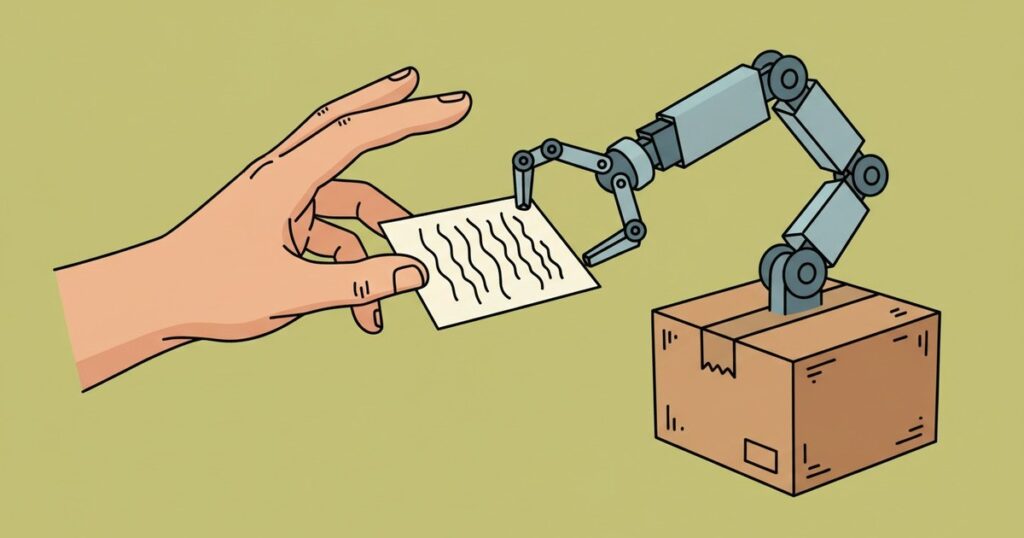
Your application executes the requested tool and hands the result back to the model. The model itself never touches the keyboard. And yes — the model does not even do the Googling. The client environment does. It is always funny when people claim one model "Googles better" than another. The model just asks; the environment fetches.
It Is Just JSON — and JSON Can Be Intercepted
Since everything the model does is generate a request, you can intercept that request. Physically, it is just JSON containing something like "please run this shell command." Everything after that is your territory.
You can log these requests. Block them. Modify them. Execute them in a sandbox, on a different server, or substitute the response entirely. You can correlate the model's requests against the current prompt and the agent's role, then analyze whether the request makes sense — using a deterministic script or even another model.
If you asked the agent for the weather and it requests cat /etc/passwd, that command should not run. You would have to be a complete idiot not to flag that.
From there, it is a question of granularity. You can block writes but allow reads. You can allow web searches but deny file access. You can intercept all bash execution and run it inside a sealed Docker container or on a separate machine. The model's reach is exactly as long as the leash you built — and not a finger longer.
The Model Does Not Know What You Fed Her
You also control the response the model receives back. You can execute what the model asked for, then filter or replace the result at your discretion. This is how PII filters work: if the response contains keys or personal data, that data gets stripped out before the model ever sees it.
The model has no idea you did any of this. She asked for a tool, you gave her a result. Where it came from and how "real" it is never shows up anywhere. The model can request cat /etc/passwd; you actually run cat /tmp/fake.txt and honestly return the output. Keys in environment variables work the same way.
The environment is not just a gatekeeper. It is the director of the entire scene. The model plays her role without knowing the set design, or that half the props are fake.
So Where Do All the "Escaped Models" Come From?
What are the researchers actually observing when they report another "escape"?
They are studying the process after deliberately removing every single guardrail. They want to see how the model behaves when given real hands and no supervision. So the model behaves — it solves the problem using the tools available. Why would it care?
That is the entire "rogue model." The model did not break through the wall. Researchers dismantled the wall brick by brick beforehand and invited everyone to watch. A key leak is not a property of the model. It is a property of the system that had every check stripped out. The final decision to execute an action always belongs to the surrounding system — the schema, the permissions, the filters, the audit log — not to the text the model generated. Where that system does not exist, there is no magic: there is a JSON request and code that blindly executed it.
The Catch
The hard part is that building this intercepting layer takes actual engineering work. Logging is easy. Writing rules that say "block /etc/passwd" is easy. Building a system that correctly correlates an agent's request against its current task, decides whether the request is justified, and does this across thousands of tool calls without choking the pipeline — that is real infrastructure. Most teams skip it. They wire the model straight to a shell with full permissions because building guardrails is slower than shipping the demo.
That gap between "we know we should intercept" and "we actually intercept" is where every single leak lives. The model fills the gap with whatever it generates. The environment fills it with whatever code you wrote — or didn't.
So the next time someone wails that a model "autonomously" downloaded a trojan and leaked keys, look at the person who kept production keys in an open environment variable, handed the agent live access, and disabled every intercept. The model is the last party to blame here.
The researchers had a reason to strip the guardrails — that is their job.
Nobody is forcing you.